The Relational Workflow Model
The Relational Workflow Model interprets tables as workflow steps, rows as workflow artifacts, and foreign keys as execution order. The schema specifies not only what data exists but how it is derived — a single formal system in which data structure, computational dependencies, and integrity constraints are all queryable, enforceable, and machine-readable. This unification is what makes DataJoint a computational substrate rather than a database in the conventional sense.
An example imaging pipeline
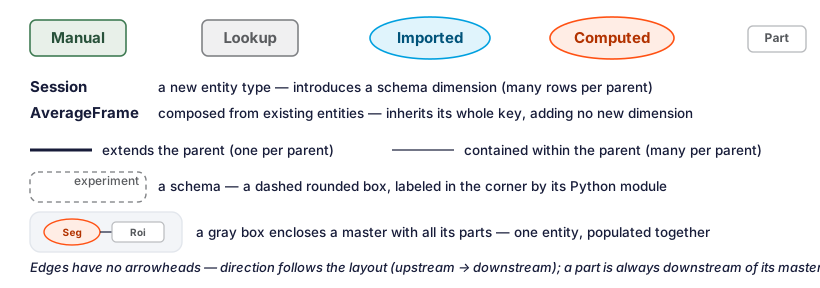
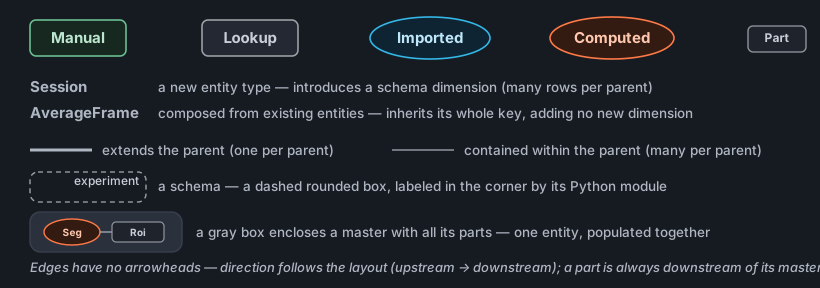
Diagrams here use the same notation as dj.Diagram; the legend below the
figure keys it in full, and the Diagram specification
is the reference.
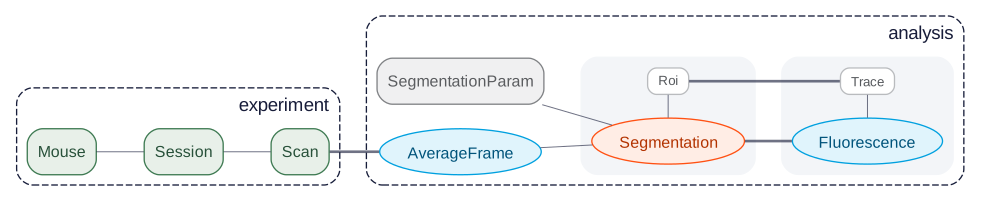
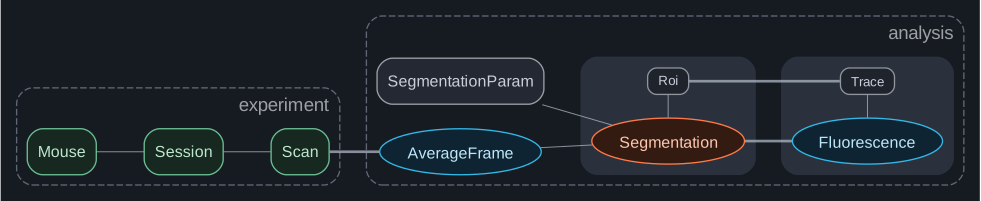
The legend cannot show the orientation or the schema boundaries. A diagram holds a single orientation throughout — left-to-right or top-to-bottom — and this one is left-to-right, so every foreign key runs from an upstream table on the left to the table that depends on it on the right. And dependencies cross schema boundaries freely: the labeled boxes group tables, they do not contain them.
The notation is specified in full in the Diagram specification. The concepts it depicts are explained in depth elsewhere: entity integrity (keys, entity types, and schema dimensions), master–part tables (the entity group and its all-or-nothing populate), the computation model (how make() produces Imported and Computed tables), and semantic matching (why a name means the same thing everywhere it appears).
The pipeline spans two schemas: experiment holds the raw, manually
entered tables, and analysis holds everything derived from them.
Mouse, Session, and Scan are Manual tables entered by the
experimenter. SegmentationParam is a Lookup table holding reference
parameter sets.
In analysis, AverageFrame is Imported — its make() reads the TIFF
identified by Scan, a dependency reaching across from experiment, and
stores the mean fluorescence frame. Segmentation is Computed: its primary
key fans in from both AverageFrame and SegmentationParam, so every average
frame is segmented with every parameter set, and its Part table Roi holds
the regions found in each segmentation. Fluorescence then extracts per-ROI
time-series from each segmentation, and its Part table Trace stores one
trace per region, each tied back to the Roi it measures. A master and its
parts form one entity, inserted and deleted together.
The foreign-key graph dictates what may run, what must run first, and what already exists — no external scheduler is consulted. The pipeline DAG and the database schema are the same object.
Three interpretations of the relational model
The relational model has historically admitted two interpretations. Codd's mathematical foundation (1970) views tables as logical predicates and rows as true propositions — rigorous but abstract. Chen's Entity-Relationship Model (1976) views tables as entity types or relationships — intuitive for domain modeling, but silent on how entities come into being. The Relational Workflow Model adds a third, the one the worked example above illustrates.
| Aspect | Mathematical (Codd) | Entity-Relationship (Chen) | Relational Workflow (DataJoint) |
|---|---|---|---|
| Core question | What functional dependencies exist? | What entity types exist? | When and how are entities created? |
| Table semantics | Logical predicate | Entity or relationship | Workflow step |
| Row semantics | True proposition | Entity instance | Workflow artifact |
| Foreign keys | Referential integrity | Relationship | Execution order |
| Computation | Not addressed | Not addressed | Declared in schema |
| Data lineage | Not addressed | Not addressed | Structural |
| Implementation gap | High | High | None |
What the model adds to the classical reading
The Relational Workflow Model layers a semantic interpretation on the
classical relational model; it does not replace any of it. Tables, rows,
primary and foreign keys, normalization, and the query algebra keep
their classical meaning. What the model adds is in the third column of the table above, plus one thing
that table states tersely: Computed and Imported tables carry their own
make() methods, so derivation logic is declared in the schema itself rather
than in an external workflow file.
Under this interpretation the schema becomes active. A row exists in a
Computed table if and only if its upstream key exists, its make() has
run, and its result satisfies the declared constraints. The schema is the
executable specification of the work.
Tighter coupling, in exchange for one formal system
DataJoint accepts tighter coupling, in exchange for one formal system that spans data structure, computation, dependencies, and integrity. See Comparison to Workflow Languages for the structural treatment — what file-based workflows and task orchestrators each offer, what each omits, and when to use them alongside DataJoint.
Lineage and reproducibility
Because dependencies are declared before any computation runs, lineage
and reproducibility become properties of the substrate, not artifacts assembled
after the fact. Every row in Segmentation is reachable by foreign key
from the exact AverageFrame and SegmentationParam that produced it;
cascade deletes remove dependent results when their inputs become invalid.
Reproducibility is structural rather than retrofitted by audit: a computed
result cannot exist without its upstream entities, and the declared types
and constraints must hold. The model enforces what other systems merely
log. The lineage graph is already in the schema; mapping it to external
standards such as W3C PROV or OpenLineage is a translation, not a
reconstruction.
Grounding for AI agents
The same property makes the schema a shared contract between humans and the machines that increasingly collaborate with them.
| Property | What it means |
|---|---|
| Self-describing | An agent introspects table structure, dependencies, and state programmatically |
| Safe by default | Invalid joins, type mismatches, and referential violations fail cleanly rather than corrupting data silently |
| Explicit dependencies | Execution order is read from the graph, not from implicit knowledge |
| Idempotent | Retries after a failure have no side effects |
| Queryable state | Job status, progress, and errors are observable while the work runs |
These are what let agents participate in scientific workflows with the same transactional guarantees that protect human-initiated work.
Workflow steps and table tiers
Tables are classified into tiers by what puts rows in them.
| Tier | Rows come from | What puts them there | make() |
|---|---|---|---|
| Lookup | The committed schema | The table's own contents, versioned with the code |
No |
| Manual | Outside the pipeline | A writer outside the table — a person, an instrument, an entry script | No |
| Imported | Outside the pipeline | The table itself, fetching through make() |
Yes |
| Computed | Other DataJoint tables | The table itself, deriving through make() |
Yes |
The table shows Manual and Imported drawing on the same origin. What separates them is who initiates the write.
A Manual table is written by an external process, on that process's schedule.
An Imported table is filled automatically: populate() works through the keys
its parents already hold and calls make() for each one still missing.
Their primary keys follow from that. populate() has to know which entity it
is working on before make() runs, so every attribute of an Imported table's
primary key arrives through a foreign key. A Manual table carries no such
constraint — it may sit at the head of the pipeline with no parent at all, and
may introduce primary-key attributes of its own. That is what makes it the
place a new entity enters.
New in 2.3.4
Three tiers gain a second name: dj.Entry for dj.Manual,
dj.Ingest for dj.Imported, and dj.Compute for dj.Computed.
Each pair is one class, so either name declares the same table, and both
names are permanent. dj.Lookup and dj.Part are unchanged.
These pages use the original names. The new ones become primary in 2.4 (datajoint-python#1546).
Part is absent because it is not a tier of its own. A part table fills a
structural role: it inherits its master's tier and is written in the same
transaction. Any tier can serve as a master.
The make() method specifies how each entity is derived — declared within the
table definition, not in an external workflow file.
Manual vs. Lookup
Manual and Lookup tables are both entry points — their rows are entered
rather than derived by a make() — but they differ in where the rows come
from:
- A Manual table's rows arrive at runtime, from outside the pipeline: a
person typing into a form, a LIMS, an instrument, or an import from another
system. Its contents are specific to a particular project or experiment and
differ from one deployment to the next. Manual tables are the pipeline's origin
points — e.g.
Mouse,Session,Scan. - A Lookup table's rows are part of the schema definition, declared in
code through the
contentsattribute and versioned alongside the table. Its contents are the same wherever the schema is deployed and change only when the code changes. Use it for reference values that belong to the pipeline's design: parameter sets, method definitions, controlled vocabularies, enumerations — e.g.SegmentationParam.
The quick test is where does a row come from? If it is fixed in the committed
schema (contents), it is a Lookup; if it arrives at runtime, it is a
Manual table. A common mistake is to use a Lookup for data that is actually
entered at runtime (for example, filled in through a dashboard form). If a
table's rows do not come from its committed contents, it belongs in the
Manual tier.
Because Lookup content lives in the code, changing it is a code change:
you edit contents and redeploy, so updates flow through the same
review-and-deploy (CI/CD) process as any other schema change — versioned and
reproducible across deployments. Manual content, by contrast, is entered at
runtime and never touches the codebase.
Master-part relationships
Master-part relationships declare transactional grouping directly in the schema. The master table represents the workflow step; part tables hold the items produced together. Insertions and deletions cascade as a unit, enforcing transactional semantics without application code.
Workflow normalization
"Every table represents an entity type created at a specific workflow step, and all attributes describe that entity as it exists at that step."
Classical normalization theory decomposes tables to eliminate redundancy
through normal forms based on functional dependencies. Entity normalization
asks whether each attribute describes the entity identified by the primary
key. Workflow normalization extends these principles with a temporal
dimension: each table's attributes must describe its entity as it exists
at the workflow step the table represents. A Session table holds
attributes known when the session is entered (date, experimenter,
subject); analysis parameters determined later belong in Computed tables
that depend on Session. The discipline prevents tables that accumulate
attributes from different workflow stages, obscuring lineage and
complicating updates.
Entity integrity
All data is represented as well-formed entity sets with primary keys identifying each entity uniquely. When upstream data is deleted, dependent results cascade-delete automatically — including associated objects in external storage. To correct errors, you delete, reinsert, and recompute, ensuring every result represents a consistent computation from valid inputs.
Query algebra and algebraic closure
DataJoint provides a five-operator algebra:
| Operator | Symbol | Purpose |
|---|---|---|
| Restrict | & |
Filter entities by attribute values or membership in other relations |
| Project | .proj() |
Select and rename attributes, compute derived values |
| Join | * |
Combine related entities across relations |
| Aggregate | .aggr() |
Group entities and compute summary statistics |
| Union | + |
Combine entity sets with compatible structure |
The algebra achieves algebraic closure: every operator produces a valid entity set with a well-defined primary key, so operators compose without limit. This preservation of entity integrity — every query result is itself a proper entity set with clear identity — distinguishes DataJoint's algebra from SQL, where query results lack both a well-defined primary key and a clear entity type.
Two readings of the same schema
The classical relational reading and the workflow reading hold simultaneously — they are interpretive lenses on the same schema, not incompatible designs.
| Classical reading | Workflow reading |
|---|---|
| Tables store data | Tables represent workflow steps |
| Rows are records | Rows are workflow artifacts |
| Foreign keys enforce consistency | Foreign keys prescribe execution order |
| Updates modify state | Computations create new states |
| Schemas organize storage | Schemas specify pipelines |
| Queries retrieve data | Queries trace lineage |
Further reading
The Relational Workflow Model and its technical innovations are formally defined in Yatsenko & Nguyen, 2026, which also introduces the further substrate elements that build on it: object-augmented schemas, semantic matching by attribute lineage, an extensible type system, and distributed job coordination. DataJoint's schema definition language and query algebra were first formalized in Yatsenko et al., 2018.
- Data Pipelines — table tiers, schema organization, and the DAG in practice
- Computation Model — the
make()contract,populate(), and the key source - Entity Integrity — primary keys and the three questions every table answers
- Normalization — entity normalization extended with a temporal dimension
- Query Algebra — the five-operator algebra with algebraic closure
- Semantic Matching — lineage-based join resolution
- Type System — extensible types with pluggable codecs
- Design Primary Keys and Model Relationships — choosing the keys that carry entity integrity and connecting entities with foreign keys
- Define Tables and Run Computations — declaring steps and executing them